ต้นทุน API ของการพัฒนาเกม AI
Updated 2026-09-05
วางงบเส้นทางไปยัง playable slice ที่ accepted แยก text coding, image production, repairs ที่ล้มเหลว และงานมนุษย์เพื่อให้ยอดรวมอธิบายสิ่งที่สำเร็จ
ประเมิน workflow ไม่ใช่ initial prompt
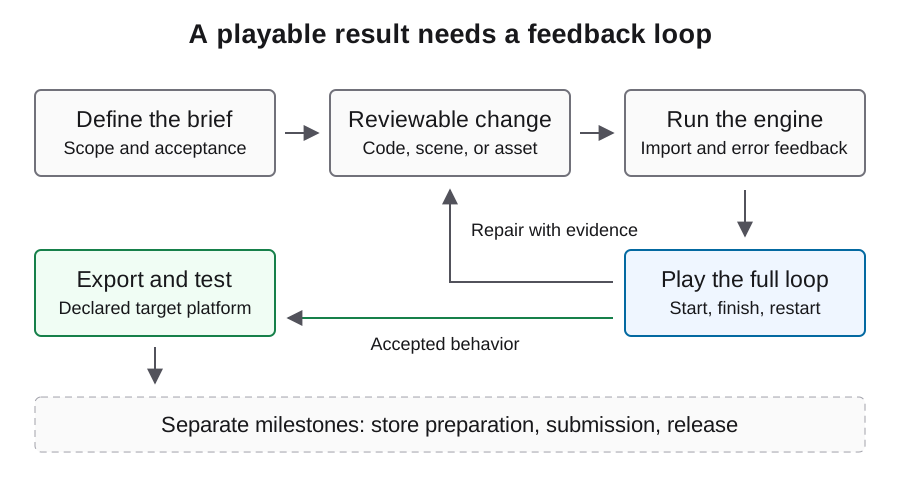
session พัฒนาเกมอาจอ่าน source เสนอ edits ตีความ engine errors ตรวจ screenshots และ retry งานที่ fail ซ้ำ initial brief เป็นเพียง input เดียว เริ่มงบจาก accepted milestone ขนาดเล็ก เช่น รอบสมบูรณ์และ restart แทนการคิดว่า request เดียวจะให้ deliverable
ลิสต์ขั้นตอนที่คาดว่าจะต้องจ่าย: implementation, debugging, asset work, localization และ review ระบุว่าอะไร run local และอะไรเรียก billable service ใช้ pilot เพื่อเรียนรู้ว่า usage สะสมตรงไหนก่อนอนุมัติงบใหญ่ estimate ควรอธิบาย assumptions ไม่ใช่ทำให้เหมือน invoice ที่วัดแล้ว
ใช้ ledger แยกสำหรับ resource แยก
ใช้หมวดแยกสำหรับ text-model calls, image generation, audio services, local engine work และ human intervention local compile ไม่ได้ใช้ model tokens โดยตัวมันเอง แต่การส่ง log กลับให้เอเจนต์อาจสร้าง request ใหม่ assistant เดียวอาจ orchestrate ทั้งหมดโดยไม่ได้ทำให้ billing units เหมือนกัน
แยก subscription activity จาก API usage หากจัดสรรค่า subscription บางส่วนให้โปรเจกต์เพื่อ budget ภายใน ให้ระบุว่าเป็น allocation rule ไม่ใช่ observed per-request charge เช่นเดียวกันอย่านับ API spend ของ development task เป็น cost ที่เกิดกับผู้เล่นทุกคนของเกม offline ในอนาคต
| หมวด | บันทึก | คำถามด้านงบ |
|---|---|---|
| Text coding | provider usage และ model identity จริง | repair stage ใดใช้ requests? |
| Image หรือ audio production | request และ billing records เฉพาะ service | output กี่รายการถึง acceptance? |
| Engine work | local execution time และ environment | build หรือ import work block progress ที่ใด? |
| Human review | interventions และ review time | อะไรยังต้องแก้ด้วยมือ? |
เก็บ request records ก่อน aggregate
กำหนด run identifier และ stage ให้แต่ละ operation เก็บ provider request identifiers ที่เปิดเผย model identity จริง outcome usage และ reference ไปยัง billing evidence sanitize credentials ก่อน export logs record ตัวอย่างด้านล่างจงใจให้ค่าที่ไม่ได้สังเกตเป็น null
อย่าอนุมาน request สำเร็จจาก local file ที่ accepted หรือ zero charge จาก timeout usage บางส่วนมาหลัง client เสีย connection กระทบยอด provider record ก่อนสรุปยอดและเก็บรายการที่ยังไม่ match ให้เห็น วิธีนี้ทำให้ experiment ซ้ำเปรียบเทียบได้โดยไม่เปลี่ยน telemetry gaps เป็น savings ปลอม
{
  "run_id": "game-pilot",
  "stage": "controller-repair",
  "provider_request_id": null,
  "model_id": null,
  "outcome": "not_started",
  "usage": null,
  "billed_amount": null,
  "currency": null,
  "billing_evidence": null,
  "accepted_artifact_hash": null
}
ใช้ pricing contract ของ provider จริง
ใช้ provider และ service tier ที่จัดการ request พร้อม rate schedule ที่ใช้กับ billing record นั้น ราคา OpenAI อย่างเป็นทางการอธิบาย token และ tool categories ส่วนราคา APIsRouter เป็น commercial source แยก อย่าแทนที่กันโดยไม่บอก
สำหรับ estimate คูณแต่ละ billable category ด้วย rate ที่ใช้ได้ แล้วบวก service-specific charges ตรวจว่า provider รายงาน cached input, output และ tool usage อย่างไรเพื่อไม่ให้ double count ระบุ currency และ conversion assumptions ชัด ใช้ settled charge ของ provider เมื่อต้องกระทบยอด actual spend และเก็บ estimate แยกเพื่ออธิบายความต่าง
วาง stop conditions รอบ repair loops
ตั้ง budget ceiling และ checkpoint หลังแต่ละ accepted milestone จำกัด automatic retries และกำหนดอาการที่ต้องให้คนวินิจฉัย เช่น edits ซ้ำแต่ reproduction เดิมไม่เปลี่ยน provider spending control และ agent task limit ปกป้องคนละ boundary ใช้ทั้งคู่เมื่อมีและตรวจพฤติกรรมของแต่ละตัว
ลด context ที่ไม่จำเป็นด้วยการส่ง scene ที่เกี่ยวข้อง changed files และ error แรกที่มีความหมาย เก็บ state พอไม่ให้แนวทางที่ fail ถูกทำซ้ำ อย่าลบ evidence สำคัญเพียงเพื่อย่อ input request ที่ถูกกว่าแต่สร้าง blind repair ใหม่อาจเพิ่ม cost ของผลลัพธ์ที่ accepted
เปรียบเทียบโมเดลบน acceptance path เดียวกัน
คง brief, project baseline, target และ acceptance criteria ให้เหมือนกัน บันทึก failed attempts และ human assistance ของแต่ละโมเดล เปรียบเทียบ reconciled spend รวมและ behavior ที่ accepted ไม่ใช่แค่ token price หรือคุณภาพที่ดูดีของ response แรก
จัด task categories ต่างกันหลัง pilot แสดงว่าผ่านมาตรฐานที่ต้องการแล้วเท่านั้น string handling ที่ตรงไปตรงมา gameplay diagnosis ที่ยาก และ visual review อาจต้องการสิ่งต่างกัน โมเดลที่เก่งกว่าอาจลด iterations แต่เป็นเพียง hypothesis จน same-task record รองรับ หลีกเลี่ยง recommended-model list ที่หมุนไปจน stale หรือสื่อ availability ที่ยังไม่ verify
แยก game production จาก runtime economics
เกม offline ที่ export แล้วใช้ deterministic logic ปกติหลังพัฒนาได้ หากเพิ่ม dialogue ที่สร้างโดย live model หรือ runtime features อื่น ให้สร้างงบแยกที่ครอบคลุม player behavior, service failures, abuse controls และ continuing operations เก็บ secrets หลัง service boundary ที่เหมาะสมแทนการฝัง provider key ใน game client
อย่าประเมิน runtime budget ด้วยการคูณ development tokens กับยอดขาย วัด request pattern ของ feature จริงในการทดสอบที่ได้รับอนุญาตและตรวจ platform requirements ที่ใช้ Image assets ที่สร้างครั้งเดียวตอน production และภาพที่สร้างให้ผู้เล่นตอน runtime ก็เป็นคนละ cost models
หลักฐานและเคส Astra
model identity ของ game prototype ยังไม่ผ่านการยืนยันจนกว่าจะมี Astra evidence ชัดเจน ยืนยัน provider, access mode และ model identity จริงก่อนใช้ rate กับเคสนี้ ใช้ provider billing record แทนการเดา charge จากชื่อโมเดลใน development brief
หน้านี้ไม่มี game budget ที่วัดแล้ว ledger และขั้นตอนจัดงบเป็นวิธีเพื่อให้ได้มา final report ที่มีประโยชน์ควรระบุ accepted milestone, artifact identity, actual API spend, asset charges แยก human work และ billing entries ที่ยังไม่กระทบยอด เพื่อให้ผู้อ่านตัดสินได้ว่าการใช้จ่ายทำอะไรสำเร็จ
คำถามที่พบบ่อย
เกมที่สร้างด้วย AI หนึ่งเกมมีต้นทุนเท่าไร?
ไม่มีตัวเลขสากลที่เชื่อถือได้ Scope, repair loops, assets, access mode และ human review เป็นตัวกำหนด workflow วัด playable slice ขนาดเล็กที่ accepted ก่อน
ควรตัด failed requests ออกหรือไม่?
เก็บใน ledger และกระทบยอด billing outcome การทำงาน client ที่ fail ไม่ได้แปลว่า provider usage เป็นศูนย์เสมอ
image costs เป็นส่วนหนึ่งของ Astra text coding หรือไม่?
บันทึก image-generation service charges แยก การที่เอเจนต์ประสาน call ไม่ได้ทำให้ image service และ text model เป็น billable resource เดียวกัน
subscription usage เหมือน API cost หรือไม่?
ไม่ แยก subscription activity และ actual API charges การจัดสรรค่า subscription ภายในต้องติดป้ายด้วย accounting rule
metric ใดมีประโยชน์กว่า cost per prompt?
reconciled spend รวมของ accepted milestone พร้อม intervention และ defect records มันเชื่อม expenditure กับผลลัพธ์ที่ผู้เล่นใช้ได้