Usage से accepted work तक Astra API costs
Updated 2026-09-05
Ordinary input, cache reads, cache writes और output को अलग account करें। Current official rate card और complete request ledger से task का estimate बनाएँ।
Rate चुनने से पहले billing system चुनें
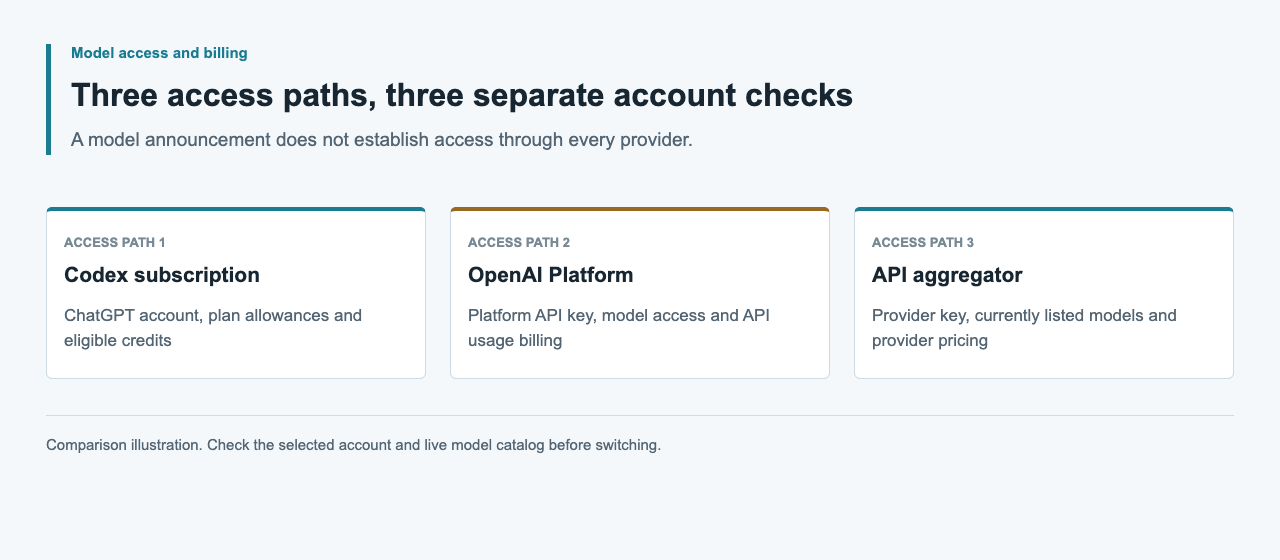
Direct Astra API requests OpenAI Platform billing उपयोग करती हैं। ChatGPT-authenticated Codex work subscription या workspace allowances और credits उपयोग करती है। OpenAI इन्हें अलग publish करता है, इसलिए Codex credit rate API token की dollar price नहीं और included subscription turn API receipt नहीं है।
Direct requests के लिए official API pricing page खोलें और service tier, context band तथा processing arrangement पर लागू gpt-6-astra rates चुनें। Rate-card URL और observation date estimate के साथ रखें। Request-level usage से calculation बनाएँ, फिर total को Platform usage records और bill से compare करें। इससे rate selection या missing requests का अंतर ढूँढना आसान होगा।
Exact Responses usage fields capture करें
Official prompt-caching guide input_tokens, input_tokens_details.cached_tokens और input_tokens_details.cache_write_tokens document करती है। Cached reads और cache writes input के भीतर अलग categories हैं, इसलिए ordinary input निकालने से पहले दोनों subtract करें। हर uncached token पर ordinary input rate मानने से cache लिखने वाली request की cost कम आँकी जा सकती है।
Reasoning guide output_tokens और output_tokens_details.reasoning_tokens document करती है। Reasoning tokens output usage में शामिल हैं; उन्हें दूसरी billed token category के रूप में फिर add न करें। total_tokens को usage total रखें, जिसे एक blended rate से multiply न करें। पूरा usage object record करें, ताकि बाद में reconciliation अधूरे text-only log पर निर्भर न हो।
| Responses field | Meaning | Accounting treatment |
|---|---|---|
| usage.input_tokens | Total input tokens | Ordinary input, cache reads और writes अलग करें |
| usage.input_tokens_details.cached_tokens | Cached input tokens | Cached-input rate लागू करें |
| usage.input_tokens_details.cache_write_tokens | Cache में लिखे गए input tokens | Cache-write rate लागू करें |
| usage.output_tokens | Reasoning समेत output tokens | Output rate एक बार लागू करें |
| usage.output_tokens_details.reasoning_tokens | Output के भीतर reasoning | Diagnostic subset के रूप में रखें |
| usage.total_tokens | कुल input और output usage | Reconciliation के लिए सुरक्षित रखें |
Double counting के बिना token subtotal निकालें
मान लें I input tokens, C cached input, W cache-write input और O output tokens हैं। Ordinary input I - C - W होगा। यदि R_input, R_cached, R_write और R_output समान currency में प्रति million tokens rates हैं, तो token subtotal ((I - C - W) * R_input + C * R_cached + W * R_write + O * R_output) / 1,000,000 होगा।
नीचे का offline function observed usage और अलग चुने गए rate card को स्वीकार करता है। उसके rate names application variables हैं, API fields नहीं। Missing या inconsistent inputs पर यह null लौटाता है, unknown usage को चुपचाप free मानने के बजाय। Result में केवल tokens हैं, tools, taxes या अन्य bill items नहीं।
function estimateTokenCost(usage, rates) {
  const I = usage?.input_tokens
  const C = usage?.input_tokens_details?.cached_tokens
  const W = usage?.input_tokens_details?.cache_write_tokens
  const O = usage?.output_tokens
  const tokens = [I, C, W, O]
  const prices = [rates?.input, rates?.cached, rates?.write, rates?.output]
  if (!tokens.every(n => Number.isSafeInteger(n) && n >= 0)) return null
  if (!prices.every(n => Number.isFinite(n) && n >= 0)) return null
  if (C > I || W > I - C) return null
  const subtotal = ((I - C - W) * rates.input
    + C * rates.cached + W * rates.write
    + O * rates.output) / 1_000_000
  return Number.isFinite(subtotal) ? subtotal : null
}
हर request के context और service-tier rules resolve करें
Astra की official pricing ordinary input, cached input, cache writes और output को अलग तथा अलग context bands और service tiers के साथ रखती है। Formula को rates देने से पहले हर request के लिए ये rules resolve करें। Rate-card row में multiplier पहले से शामिल हो तो उसे फिर लागू न करें।
Service-tier और processing metadata response के साथ रखें और requested values से compare करें। Direct API calculation में Codex speed या credit multipliers फिर उपयोग न करें; वे अलग product price schedule के हैं। Unusual processing arrangements को applicable provider terms से reconcile करें। Wrong rate basis के साथ सही token formula भी गलत cost estimate है।
Token estimates को complete task costs से अलग रखें
एक task को कई model requests, tool calls और revisions चाहिए हो सकते हैं। हर recorded request का token subtotal जोड़ें, फिर separately billed provider tools या services को उनके actual usage और pricing के अनुसार अलग जोड़ें। Model tool call कर सकता है, इसका अर्थ यह नहीं कि tool बिना अतिरिक्त charge included है।
Infrastructure, asset-generation expenses और human review time अलग categories में रखें। Service receipts और covered time period जोड़ें और shared costs को tasks में consistent तरीके से allocate करें। Game, localization batch या research task के लिए लिखें कि total में कौन-से components शामिल हैं। Taxes और currency conversions को token rates से अलग रखें, ताकि usage subtotal और final paid amount दोनों reconcile हो सकें।
| Cost component | सुरक्षित रखने योग्य evidence | Combination rule |
|---|---|---|
| Model tokens | Responses usage और applicable API rates | Request subtotals जोड़ें |
| Provider tools या services | Tool usage और official pricing category | Separately billed items जोड़ें |
| Other runtime या assets | Service receipts और attribution | अलग categories में report करें |
| Human review | Recorded time और stated valuation method | API spend से अलग रखें |
Retries, incomplete work और missing usage visible रखें
OpenAI reasoning guide चेतावनी देती है कि incomplete generation visible text दिए बिना input और reasoning tokens consume कर सकती है। Returned usage को तब भी count करें जब result acceptance check fail करे। Ledger को केवल successful final answers तक सीमित न करें और answer length से spend estimate न करें।
हर attempt के लिए response identity, model, status, usage और संबंधित task रखें। Sum करने से पहले duplicates reconcile करें। Connection fail हो और usage न आए तो provider records स्पष्ट होने तक attempt को unresolved mark करें; न zero cost और न full success सिद्ध है। Bounded retries रखें, ताकि temporary fault unreviewed billable attempts की श्रृंखला न बनाए।
Accepted results और bounded work के आसपास budget बनाएँ
Measure करने से पहले accepted work की unit तय करें: tested code change, approved product-locale record या source-linked research note। Cost per accepted unit attributable task cost को accepted-unit count से divide करने पर है, और वह count nonzero हो तभी। Ratio के साथ sample और unresolved usage report करें।
Request ceiling, bounded retries और task stop condition साथ उपयोग करें। Documented max_output_tokens field reasoning समेत generation को constrain करती है, लेकिन multi-request task के लिए complete currency budget नहीं है। Account controls भी set करें और accumulated spend track करें। Smaller context या अलग reasoning settings को same acceptance criteria पर evaluate करें, guaranteed savings की तरह advertise न करें।
Provider availability और evidence: 5 सितंबर 2026
इस guide के usage fields और formula official OpenAI documentation से आते हैं। Article के लिए Astra task cost या runtime measure नहीं किया गया। 5 सितंबर 2026 को public APIsRouter pricing endpoint ने HTTP 200, success: true और 34 models लौटाए, जिनमें Astra या GPT-6 नहीं था; इसलिए यहाँ APIsRouter Astra quote नहीं है।
Direct Astra requests के लिए OpenAI की current pricing और उसके अपने offerings के लिए live APIsRouter catalog उपयोग करें। Provider comparison में matching tasks, actual model identity, accepted outputs, complete usage और applicable rates चाहिए। इन records को calculation के साथ रखें, ताकि readers estimate और reconciled task bill अलग समझ सकें।
अक्सर पूछे जाने वाले प्रश्न
Current Astra API price क्या है?
gpt-6-astra के लिए official OpenAI API pricing page उपयोग करें। अपनी request पर लागू service tier और context band चुनें, जिसमें cache-read और cache-write rates अलग हों।
क्या reasoning tokens output_tokens के अतिरिक्त charge होते हैं?
Reasoning tokens output usage में शामिल हैं। output_tokens पर output rate एक बार लागू करें; diagnosis के लिए output_tokens_details.reasoning_tokens रखें, फिर add न करें।
Cache writes formula को कैसे प्रभावित करती हैं?
Total input से cached_tokens और cache_write_tokens subtract करके ordinary input पाएँ। Applicable official rates के अनुसार ordinary input, cache reads और cache writes को अलग price करें।
क्या timeout या incomplete answer free होता है?
जरूरी नहीं। Incomplete generation tokens consume कर सकती है और timeout billing evidence unresolved छोड़ सकता है। Returned usage रखें और missing records reconcile करें, zero cost assign न करें।
APIsRouter से Astra task की cost कितनी है?
5 सितंबर 2026 की check में Astra catalog में absent था, इसलिए कोई quote नहीं है। Current offerings जाँचें; direct Astra estimates के लिए OpenAI pricing उपयोग करें।