AI quantitative research workflow
Updated 2026-09-06
Hypothesis প্রস্তাব ও implement করতে agent ব্যবহার করুন, তারপর versioned data ও reproducible experiment-কে তা evaluate করতে দিন। Model conversation ও numerical computation আলাদা রাখুন।
একটি idea-কে falsifiable experiment-এ বদলান
আপনি যে mechanism test করতে চান, observable variable, intended universe এবং কোন condition idea-টিকে reject করবে লিখে রাখুন। Agent specification-কে code-এ translate করতে সাহায্য করতে পারে, কিন্তু result দেখার পরে success criterion redefine করা উচিত নয়। Implementation question ও research question আলাদা করুন: একটি factor সঠিকভাবে calculate হয়েও useful signal না-ও হতে পারে। প্রথম code-generation request-এর আগে ছোট specification save করুন, যাতে পরের experiment original intent-এর সঙ্গে তুলনা করা যায়।
RD-Agent, Qlib ও FinRL-এর সঠিক role বেছে নিন
RD-Agent iterative implementation ও feedback-সহ research development-এর কিছু অংশ automate করে। Qlib data, model ও evaluation-এর quantitative workflow দেয়। FinRL reinforcement-learning research environment দেয়। এই project-গুলো আলাদা stage inform করতে পারে, কিন্তু interchangeable chat client নয়। LLM request agent-এর reasoning ও coding layer-এ থাকে। Feature construction, training, simulation ও metric experiment environment-এ computation consume করে। Model budget-কে complete resource budget না ভেবে দুই path record করুন।
| Component | Primary work | আপনাকে যা supply করতে হবে |
|---|---|---|
| Research agent | Hypothesis, implementation, revision | Task contract ও permitted tool |
| Qlib | Data, training, signal ও portfolio evaluation | Compatible dataset ও experiment configuration |
| FinRL | Market environment-এ policy training | Environment, reward definition ও evaluation design |
| Human reviewer | Methodology ও interpretation | Independent acceptance criteria |
Factor generate করার আগে data contract ঠিক করুন
Instrument identity, timezone, adjustment policy, calendar ও missing-value handling document করুন। US equity research-এর জন্য appropriate US dataset ও region configuration ব্যবহার করুন; অন্য market-এর example-এ label বদলালে তার assumption migrate হয় না। Fundamental বা textual feature-এর জন্য historical universe membership ও publication timestamp রাখুন। Allowed development data-তেই transformation normalize ও fit করুন। Later restatement থেকে calculate করা feature future information leak করতে পারে, accounting period অতীতের হলেও।
Official workflow structure-কে execution boundary করুন
Qlib-এর documented qrun interface configured data, model ও evaluation workflow execute করে এবং artifact record করে। Runtime-এ পুরো environment improvise করতে agent-কে না বলে reviewed configuration দিন। নিচের command official invocation pattern; filename আপনার complete configuration বোঝায়। Execution-এর আগে dataset path, region, instrument universe, benchmark এবং train/validation/test segment validate করুন। Required history বা field unavailable হলে ছোট data-loading check স্পষ্টভাবে fail করবে।
# Requires an installed Qlib environment and a reviewed configuration.
qrun configuration.yaml
Complete experiment artifact inspect করুন
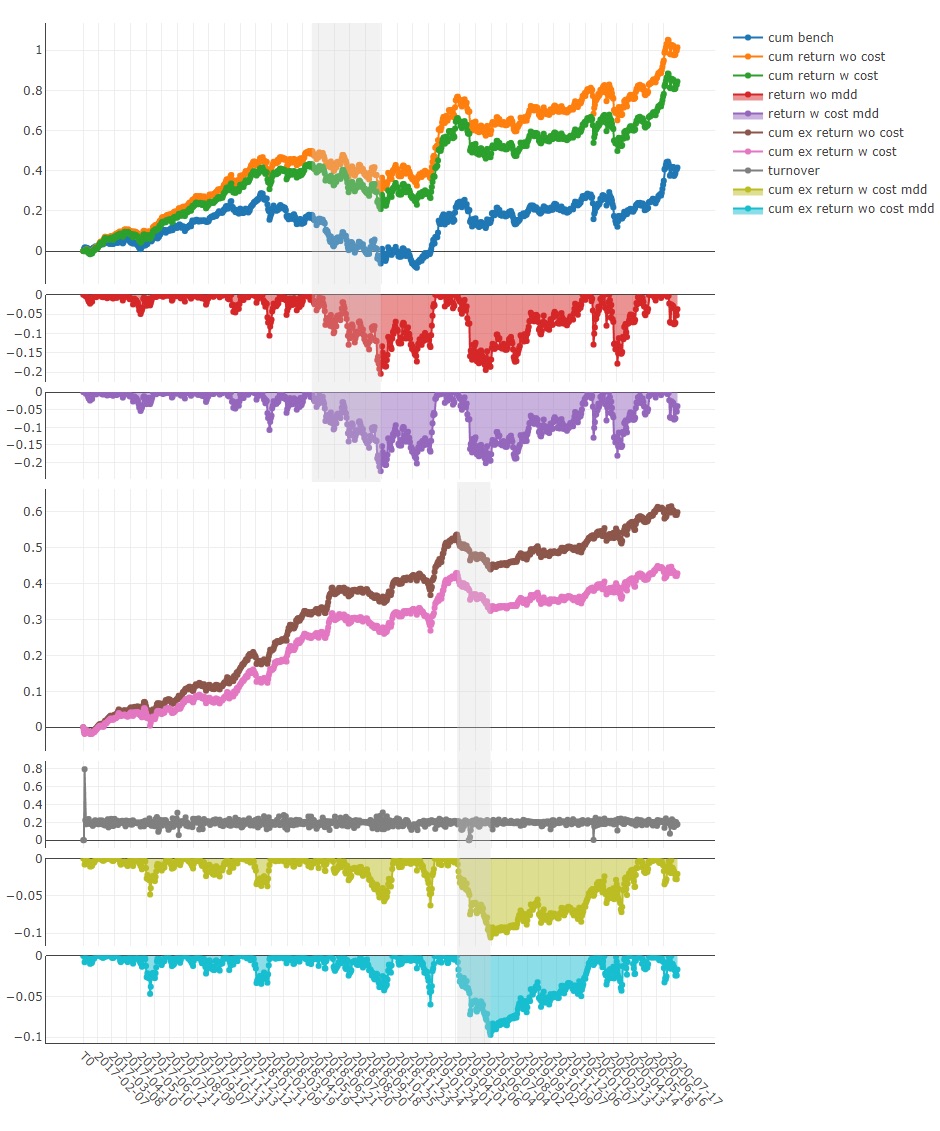
Candidate code, configuration, environment identity, প্রাসঙ্গিক হলে seed, data manifest ও recorded output একসঙ্গে রাখুন। Headline result-এর পাশাপাশি risk, turnover ও benchmark context inspect করুন। Official Qlib figure quantitative workflow যে ধরনের analysis প্রকাশ করতে পারে তা দেখায়। এটি service example, এই guide-এর result নয়। Underlying trade বা signal, input assumption ও evaluation period, unfavorable interval-সহ inspect করা গেলে তবেই chart কার্যকর।
Search process ও execution environment control করুন
Generated code-কে কেবল প্রয়োজনীয় dataset ও tool-সহ disposable, resource-bounded environment দিন। Execution-এর আগে network access, file mount ও secret exposure review করুন। Candidate revision-এর সংখ্যা limit করুন এবং rejected experiment সংরক্ষণ করুন। Agent held-out score ব্যবহার করে বারবার code improve করলে score development feedback হয়ে গেছে। সত্যিই untouched evaluation window অথবা অন্য predeclared evaluation design রাখুন। Appropriate baseline-এর বিরুদ্ধে candidate তুলনা করুন এবং শুধু final implementation নয়, প্রতিটি selection decision record করুন।
Model work ও computation আলাদা budget করুন
Hypothesis generation, code revision, embedding ও model retry request ledger-এ track করুন। Training, simulation, storage ও data access experiment ID দিয়ে joined আলাদা resource ledger-এ track করুন। Local cache repeated work কমাতে পারে, কিন্তু code ও data identity দিয়ে key করতে হবে; না হলে অন্য candidate-এর result ফেরত দিতে পারে। Iteration বা compute budget পূর্ণ হলে থামুন। Favorable result-এর জন্য agent-কে অনন্ত search করতে না দিয়ে best-supported finding ও remaining uncertainty summary করুন।
Evidence ও scope
এই walkthrough নিচে linked official RD-Agent, Qlib ও FinRL source-এর ওপর ভিত্তি করে। Configuration pattern ও service figure source-backed; এই page-এর জন্য কোনো RD-Agent loop, Qlib training run, FinRL policy বা financial return execute বা measure করা হয়নি। Version-specific model configuration-এর জন্য linked RD-Agent guide ব্যবহার করুন এবং নিজের experiment চালালে আলাদা execution record রাখুন।
সাধারণ প্রশ্ন
Qlib-এর কি LLM API key দরকার?
এর core quantitative workflow-এর দরকার নেই। Attached research agent-এর chat বা embedding credential লাগতে পারে, আর Qlib configured numerical work করে।
Factor workflow-এর চেয়ে কখন FinRL ভালো fit?
যখন research question defined environment-এ sequential policy learning নিয়ে। Environment ও reward design experiment-এর central part হয়ে ওঠে।
Agent কি test period বেছে নিতে পারে?
Development-এর আগে reviewer-এর evaluation boundary approve করা উচিত। Result দেখার পর agent-কে favorable period বেছে নিতে দিলে experiment দুর্বল হয়।
Generated factor reproducible করে কী?
Preserved code, data version, calendar ও adjustment rule, dependency version, preprocessing state এবং complete evaluation configuration।
Generated code fail করলে কী করব?
Code ও structured failure evidence রাখুন, নতুন experiment version-এ সবচেয়ে ছোট affected stage fix করুন এবং search history-তে original attempt সংরক্ষণ করুন।