AI product content की quality checks
Updated 2026-09-05
Structural validity को product meaning से अलग रखें। Local 40-row Japanese और German case में field checks pass हुए, फिर भी AI review ने Japanese wording में correction पाया।
हर field के लिए acceptance rules लिखें
हर field के लिए acceptance rules लिखें। Identity और revision fields को source से match करना चाहिए। Editable text में requested locale और required information हो तथा destination format का पालन हो। Claims को supporting evidence चाहिए। केवल एक pass या fail label यह नहीं समझा सकता कि किस condition ने product को रोक दिया।
Machine-checkable defects को editorial judgments से अलग रखें। Missing text और identifier drift को deterministic तरीके से locate किया जा सकता है। Translation benefit को बढ़ा-चढ़ाकर बताती है या नहीं, इसके लिए context और qualified review चाहिए। हर issue को उस व्यक्ति या system तक route करें जो उसे resolve कर सकता है और result को candidate revision के साथ रखें।
| जाँच | क्या जाँचता है | समीक्षा owner |
|---|---|---|
| पहचान | Product, SKU और locale mapping | catalog का owner |
| source की revision | Candidate current source से जुड़ा है | workflow का owner |
| required fields | Text और expected structure | content का reviewer |
| संरक्षित values | Price, unit और identifiers | importer का owner |
| दावे | Evidence और approved wording | product का specialist |
Assembly के बाद फिर से compare करें
केवल permitted text fields generate करें और source से copied protected values के साथ candidate record assemble करें। उस assembled record पर दूसरा comparison चलाएँ। इससे mapper की गलतियाँ और review के दौरान हुए accidental edits दोनों पकड़े जाते हैं।
नीचे का illustrative JavaScript example schema-validated objects में scalar protected values की अपेक्षा करता है। यह missing, extra या बदले हुए protected keys और stale source revision detect करके stable issue codes लौटाता है। इस helper से पहले schema और value validation करें, फिर structurally valid candidate को editorial review में भेजें।
function checkProtected(source, candidate) {
  const issues = [];
  if (candidate.sourceRevision !== source.sourceRevision) {
    issues.push({ code: "STALE_SOURCE", field: "sourceRevision" });
  }
  const keys = new Set([
    ...Object.keys(source.protected),
    ...Object.keys(candidate.protected),
  ]);
  for (const field of keys) {
    const hasSource = Object.prototype.hasOwnProperty.call(source.protected, field);
    const hasCandidate = Object.prototype.hasOwnProperty.call(candidate.protected, field);
    if (!hasSource || !hasCandidate ||
        !Object.is(source.protected[field], candidate.protected[field])) {
      issues.push({ code: "PROTECTED_FIELD_CHANGED", field });
    }
  }
  return issues;
}
Numbers और units को stored facts से जाँचें
Localized number देखने में अलग हो सकती है, जबकि stored quantity वही हो। MDN locale-aware presentation के लिए Intl.NumberFormat document करता है। Authoritative value चुनने के बाद formatting लागू करें; rendered currency string से price फिर बनाने के लिए language model को न कहें।
Numeric values के साथ units भी define करें और हर dimension की unit लिखें। Conversion authorized हो तो deterministic conversion rule उपयोग करें और original representation बचाएँ। Sentence में केवल digits compare न करें: अलग units वाले समान numbers अलग products बता सकते हैं। Missing units approval को रोकें जब तक source resolve न हो।
Placeholders की multiplicity और markup validate करें
Source और candidate से placeholders लेने के लिए application का template parser उपयोग करें। केवल names की set नहीं, counts compare करें; duplicate token sentence या application तोड़ सकता है, भले हर original token दिखाई दे। Format-specific escaping rules destination boundary पर रखें।
नीचे का छोटा check पहले से extracted tokens स्वीकार करता है। यह universal placeholder regular expression बनाने की कोशिश नहीं करता। HTML के लिए document fragment parse करें और permitted structure तथा links अलग compare करें। Custom rendering में WordPress escaping guidance relevant है, लेकिन escaping अकेले intended meaning के preservation का proof नहीं।
function samePlaceholderCounts(sourceTokens, candidateTokens) {
  const counts = new Map();
  for (const token of sourceTokens) {
    counts.set(token, (counts.get(token) ?? 0) + 1);
  }
  for (const token of candidateTokens) {
    if (!counts.has(token)) return false;
    counts.set(token, counts.get(token) - 1);
  }
  return [...counts.values()].every((count) => count === 0);
}
Luna case में structure pass हुआ, meaning review बाकी रहा
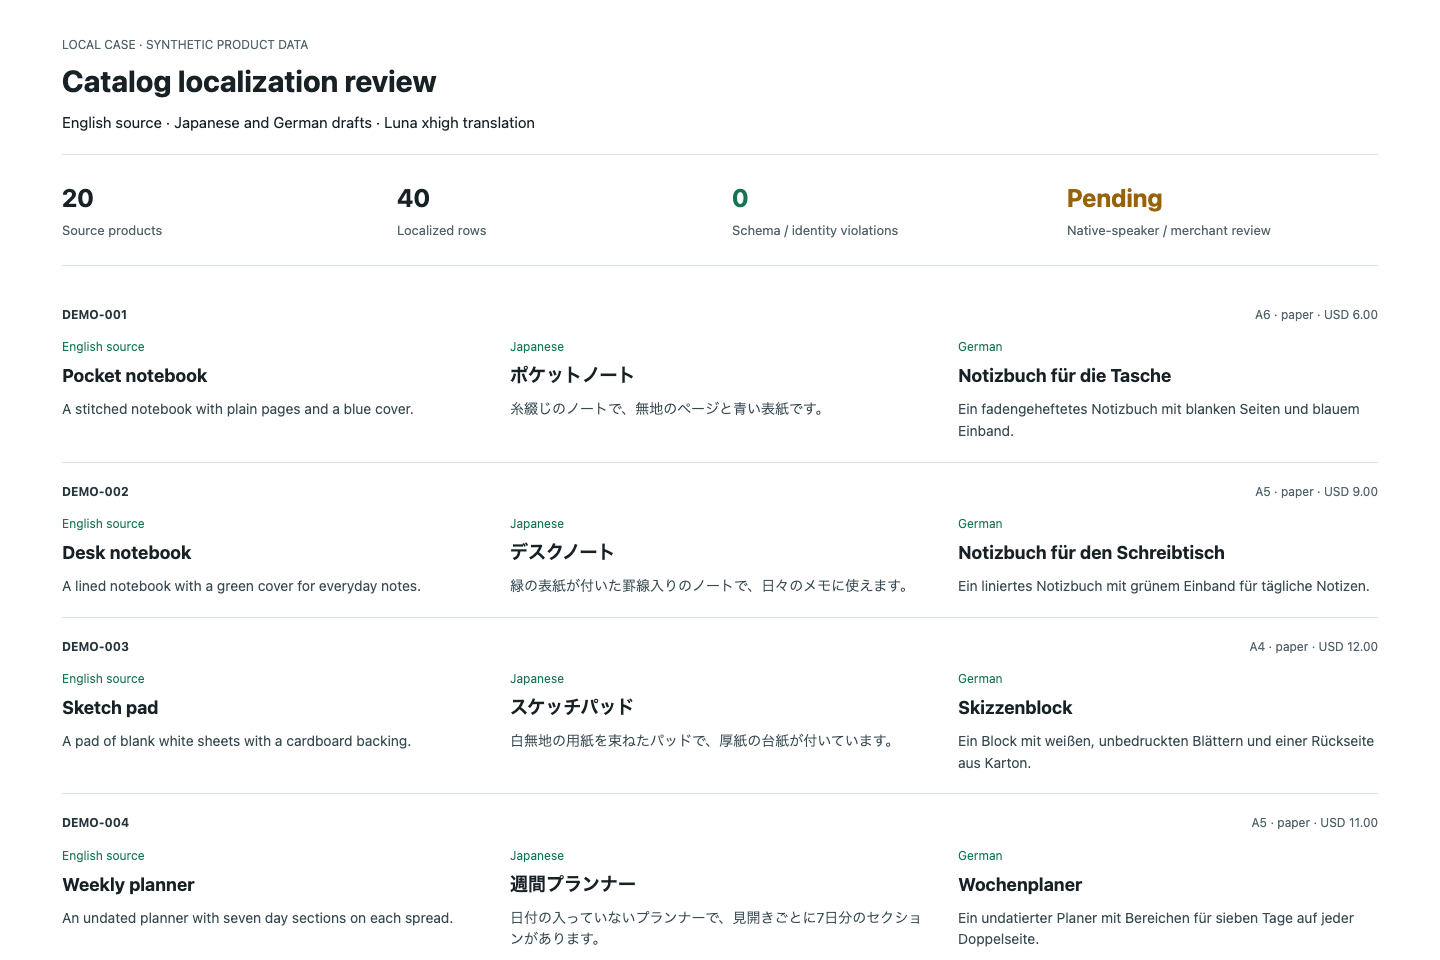
20 synthetic products से 20 Japanese और 20 German patches बनाए गए। Translation agent को gpt-5.6-luna और xhigh reasoning के लिए explicitly configure किया गया था। Deterministic schema, identity और protected-field checks सभी 40 assembled rows के लिए pass हुए। Price, currency, material और dimensions source से copy हुए; generated patches identified SKU और locale के लिए केवल title और description बदल सकते थे।
Untouched Japanese patches भी structural validator पास करते हैं। फिर भी AI review ने नीचे दिए दो wording issues पहचाने और descriptions revise कीं। Protected material field की जाँच से यह सिद्ध नहीं होता कि prose material को सही describe करती है। हर consequential assertion को source से compare करें, schema checks green होने के बाद भी।
| draft स्थिति | AI-review correction | समीक्षा boundary |
|---|---|---|
| DEMO-003 | material wording सुधारा गया | semantic review |
| DEMO-010 | Two-handle wording को स्पष्ट किया गया | semantic review |
Spreadsheet और import safety को अलग रखें
OWASP spreadsheet formula injection describe करता है और बताता है कि safety transformations अलग consumers में अलग हो सकती हैं। Supplier और generated cells को untrusted मानें। Actual spreadsheet tool के लिए reviewed serialization policy रखें और saved artifact inspect करें, केवल in-memory table नहीं।
Machine imports को review files से अलग रखें। Human viewing के लिए जो prefix लगाया जाए वह import के दौरान identifier या public description को चुपचाप न बदले। Parser से encoding, quote handling और expected row identities validate करें। Untouched source बचाएँ ताकि spreadsheet editor से आए changes पहचाने और सुधारे जा सकें।
Approval को exact candidate revision से बाँधें
Factual approval और language approval के साथ candidate revision या hash store करें। बाद का कोई edit संबंधित approval को invalidate करे, जब तक फिर review न हो। Final publisher current source revision भी compare करे, क्योंकि product specification बदलने के बाद translation unchanged होते हुए भी stale हो सकती है।
Case artifacts में corrected Japanese patches और German patches review_status: unreviewed rows में assemble होते हैं। दोनों reports translation_semantic_review: pending रखते हैं। AI-assisted correction revision step है, native-speaker या merchant sign-off नहीं। Raw और revised candidates बचाएँ और exact import text को appropriate reviewer से approve कराएँ।
Structural result को semantic acceptance न समझें
Local case का test source-field preservation, duplicate SKU, missing SKU और forbidden price override exercise करता है। Saved Japanese और German patches की read-only reassembly दोनों validated outputs reproduce करती है। Broader catalog में अपनी placeholder grammar, markup और revision policy के checks जोड़ें; ऊपर के illustrative helpers इन 40 rows के validator नहीं हैं।
यह Luna-configured local translation case था, Astra या gateway call नहीं और real store import भी नहीं। Tool ने API usage, request IDs या billing expose नहीं किए; दोनों outputs null usage और cost रखते हैं। Structural result के बाद semantic review और फिर authorized store adapter test करें।
node --test examples/commerce-localization-case/case.test.mjsअक्सर पूछे जाने वाले प्रश्न
क्या JSON-valid response import के लिए safe होती है?
नहीं। Valid syntax सही identifiers, source freshness, supported fields, accurate claims या approval सिद्ध नहीं करती। इन contracts को independently validate करें।
यदि model protected fields edit नहीं कर सकता तो comparison क्यों करें?
Assembly, mapping और review stages फिर भी mistakes ला सकते हैं। Post-assembly comparison उस actual record को जाँचता है जिसे delivery के लिए तैयार किया जा रहा है।
क्या allowed words की list से claims validate कर सकता हूँ?
Word list कुछ issues flag कर सकती है, लेकिन assertion का meaning या strength स्थापित नहीं करती। Sentence को product evidence के विरुद्ध review करें।
क्या placeholder names match करना पर्याप्त है?
नहीं। Real template parser का उपयोग करके multiplicity भी compare करें। Names की set familiar दिखे तब भी repeated या missing token defect हो सकता है।
40-row case ने क्या establish किया?
Saved patches बिना recorded structural failures assemble हुए और source-controlled product fields बचाए रहे। Japanese wording में AI-review की दो corrections फिर भी जरूरी रहीं और दोनों languages की semantic approval pending है।